MRMP Bench· a Persian benchmark for AI models
Which AI model is actually better?
Every model sits the same fixed Persian test: a 20-question report card and 8 interactive builds, from an arcade game and a santur to a Persian calendar and a 3D Azadi Tower. Code, a real browser and a jury from three companies give the score. Try every build yourself, right here.
6models published
20report-card questions · 40 points
8interactive builds · 60 points
3jurors from three companies
01Current champion
02Leaderboard
Each model’s score is the mean of its runs (a model with one run so far is “provisional”) · cost = what the model itself charged for the whole test, jury not included| # | Model | Tier | MRMP score | Report card | Showcase | Mohsen’s take | Cost of answers | Speed |
|---|---|---|---|---|---|---|---|---|
| 01 | Anthropic: Claude Opus 5.5 anthropic/claude-opus-5.5 | S | 98.59 between 97.17 and 100 | 39 / 40 | 59.59 / 60 | – | $5.12 | 137 tok/s |
| 02 | Google: Gemini 4 Argon google/gemini-4-argon | S | 90.85 between 89.23 and 92.46 | 33 / 40 | 57.85 / 60 | – | $1.33 | 85 tok/s |
| 03 | OpenAI: GPT-6 Luna openai/gpt-6-luna | S | 90.15 between 89.61 and 90.69 | 35 / 40 | 55.15 / 60 | – | 5.6¢ | 155 tok/s |
| 04 | DeepSeek V4 Flash 0423 deepseek/deepseek-v4-flash | B | 68.78 between 62.02 and 76.4 | 26 / 40 | 42.78 / 60 | – | 2.3¢ | 112 tok/s |
| 05 | Z.ai: GLM 5.3 FlashX z-ai/glm-5.3-flashx | C | 62.9Provisional | 34 / 40 | 28.9 / 60 | – | 68.9¢ | 258 tok/s |
| 06 | Qwen3.8 Flash qwen/qwen3.8-flash | C | 54.34 between 52.96 and 55.71 | 29 / 40 | 25.34 / 60 | – | 31.6¢ | 72 tok/s |
Costs are in US dollars.
03Best build per challenge
The best build of each showcase challenge. Open a card to see every model’s build for that challenge.Simorgh FlightS1
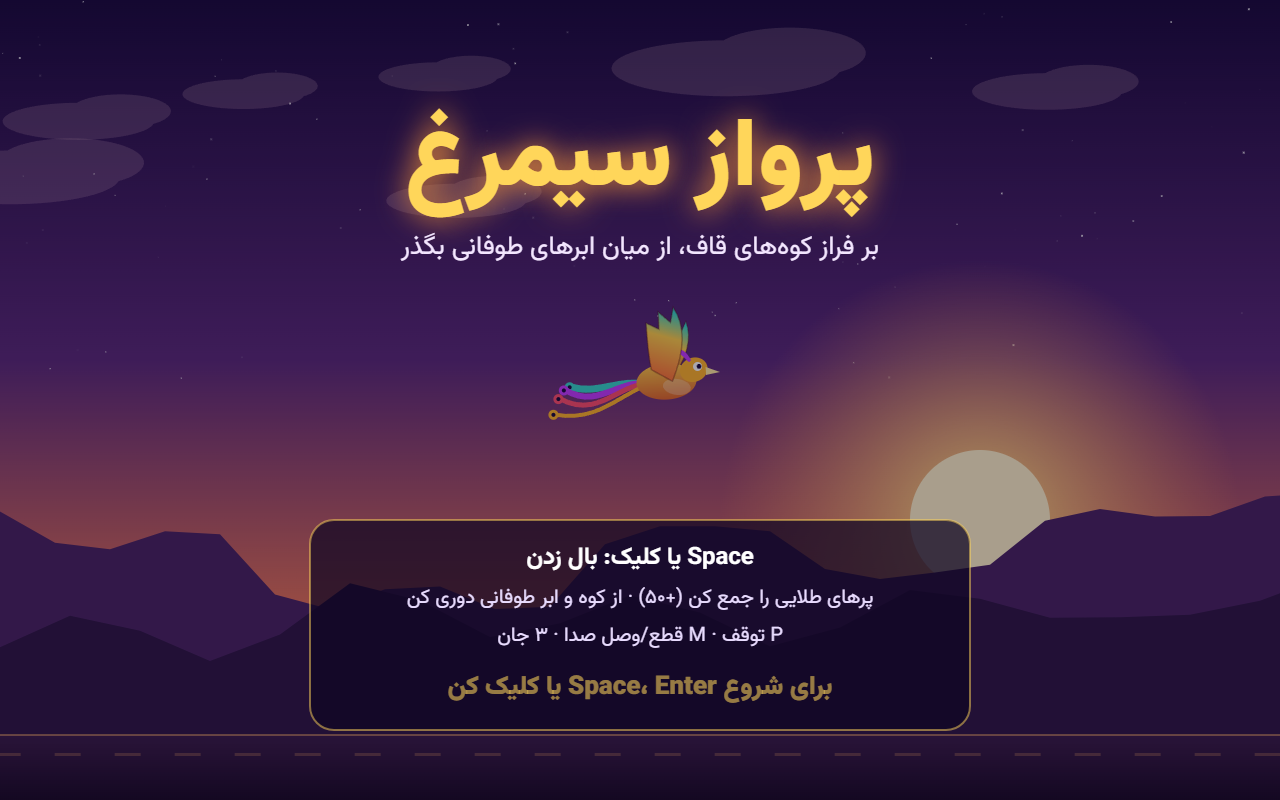 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
Ant ColonyS2
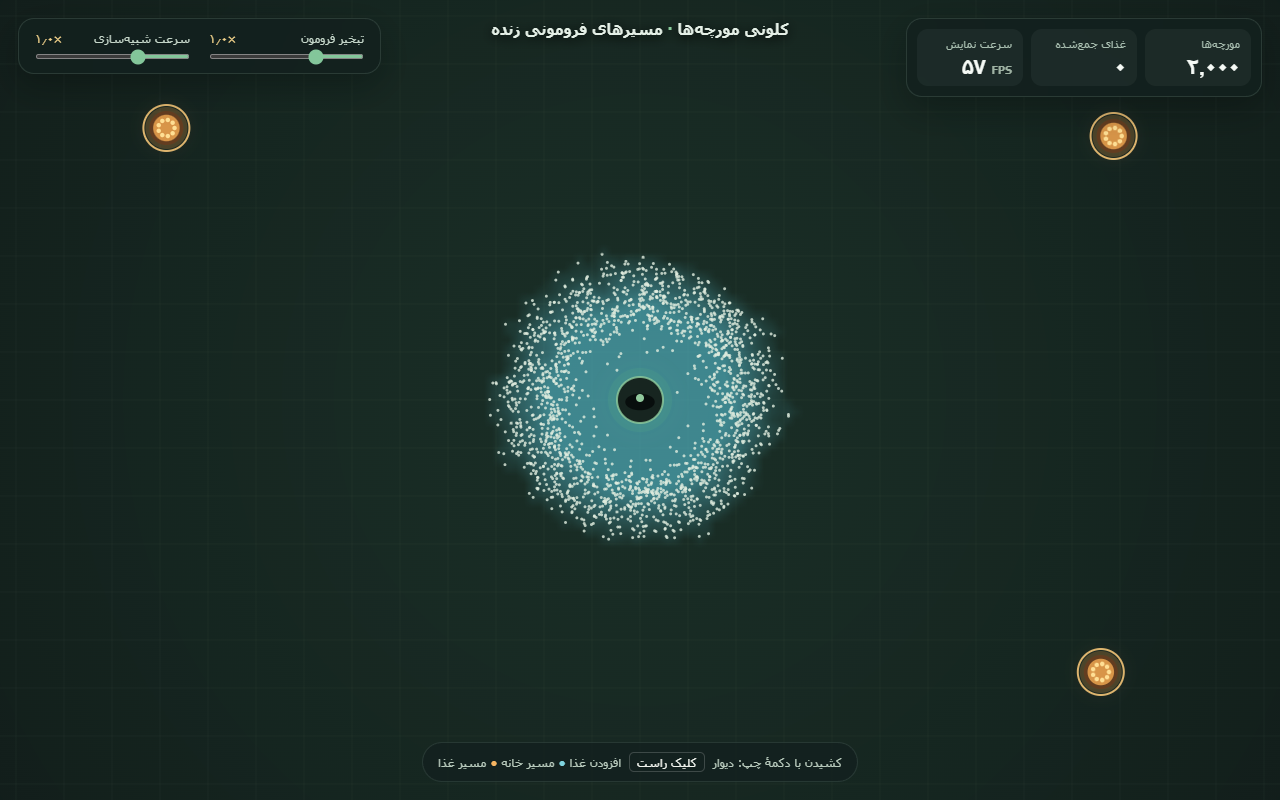 OpenAI: GPT-6 Luna · 7.5 of 7.5
3D Azadi TowerS3
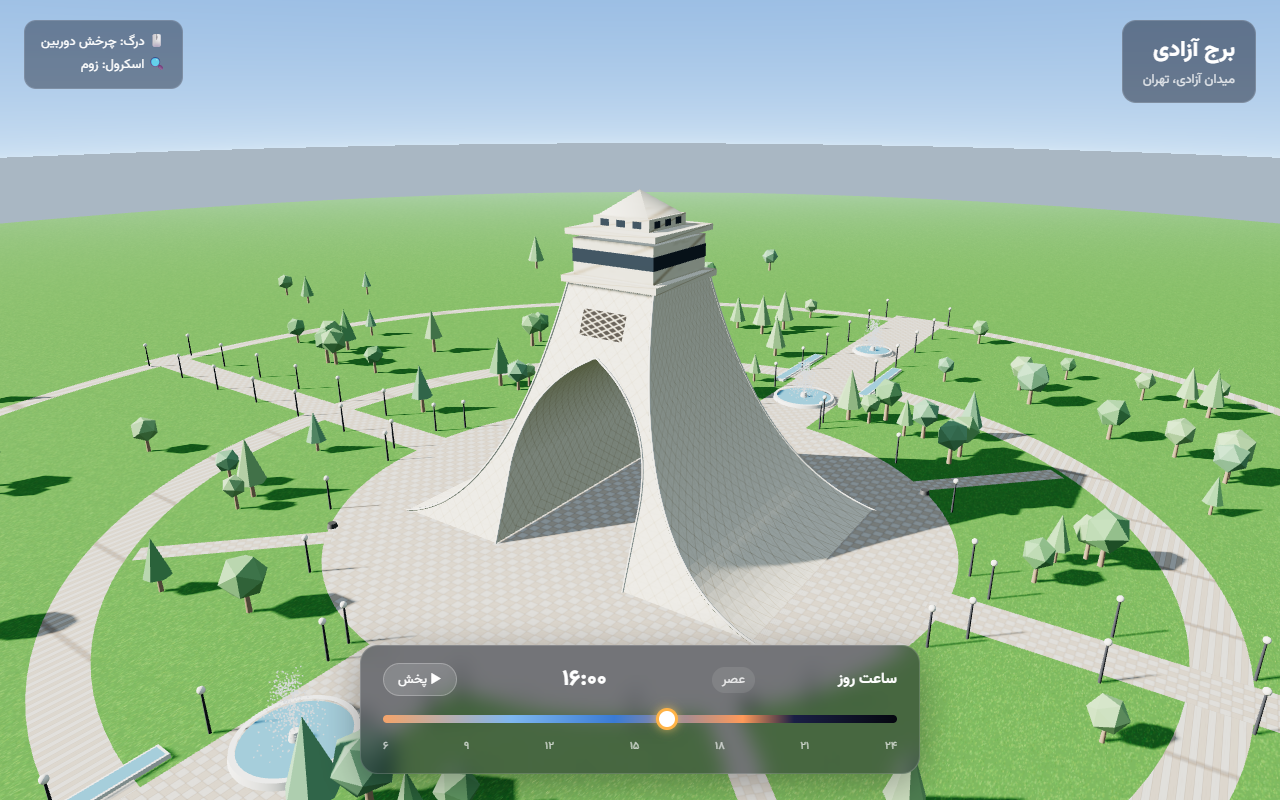 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
Virtual SanturS4
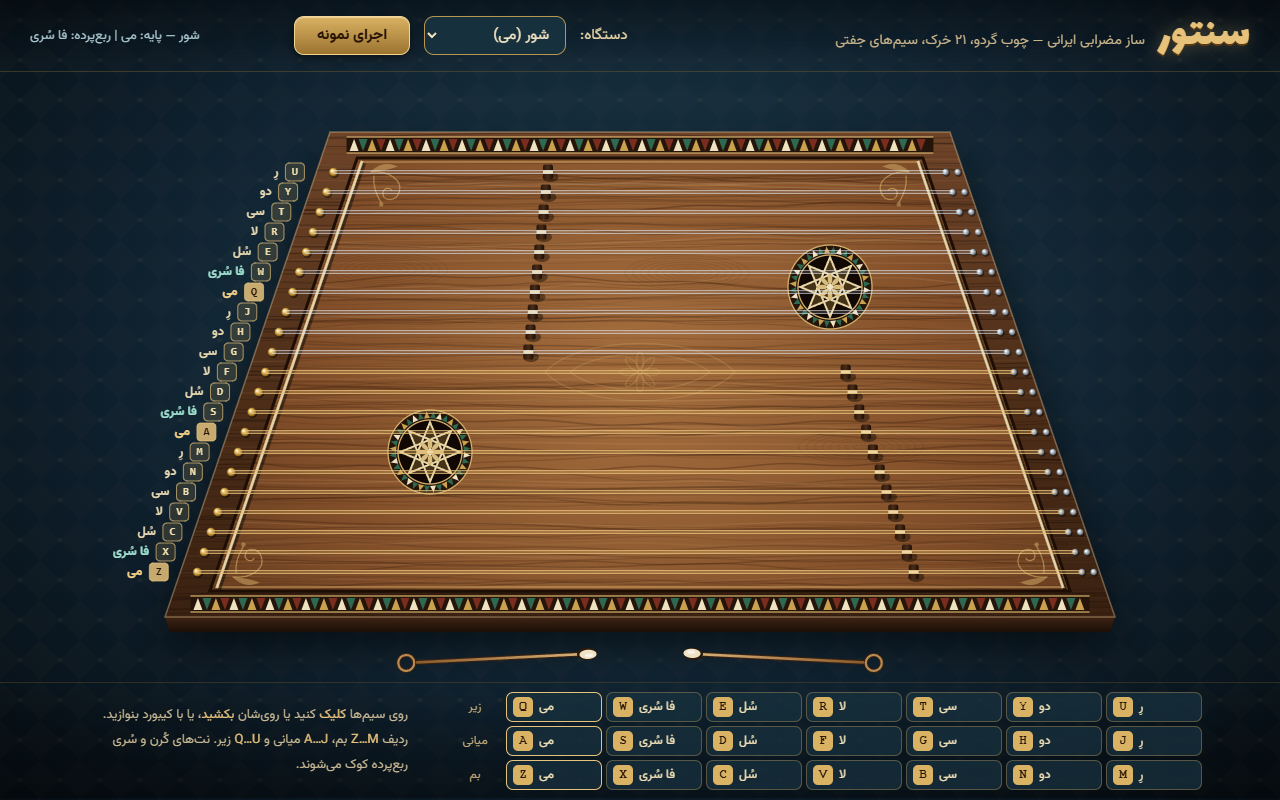 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
Autumn Book CaféS5
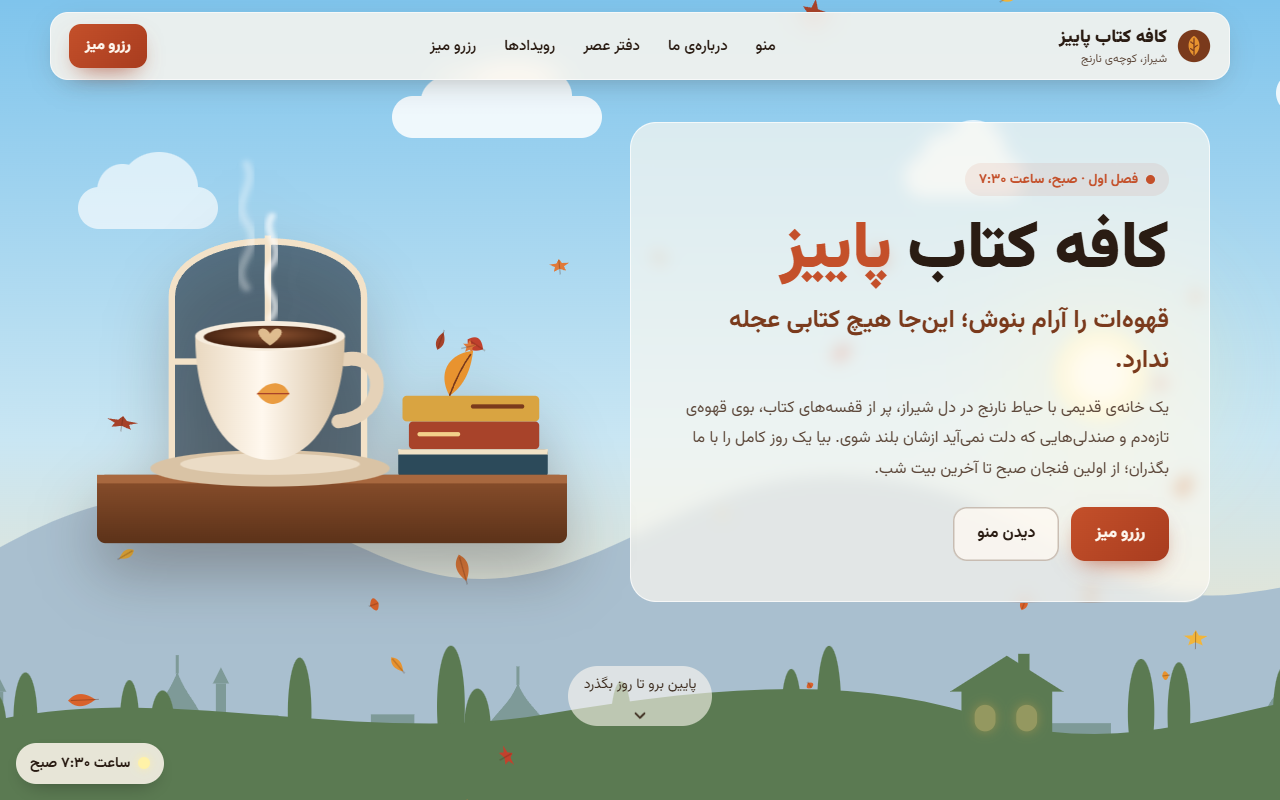 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
Persian CalendarS6
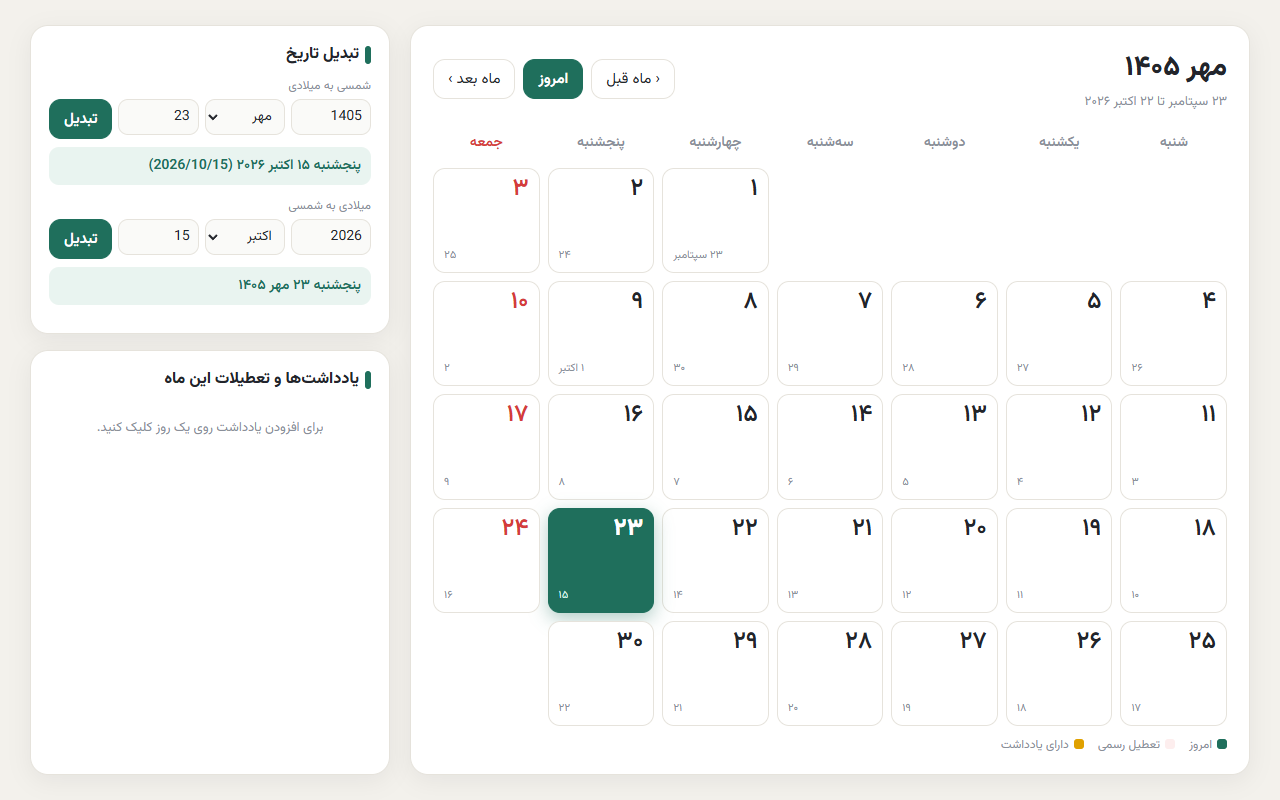 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
Girih TilesS7
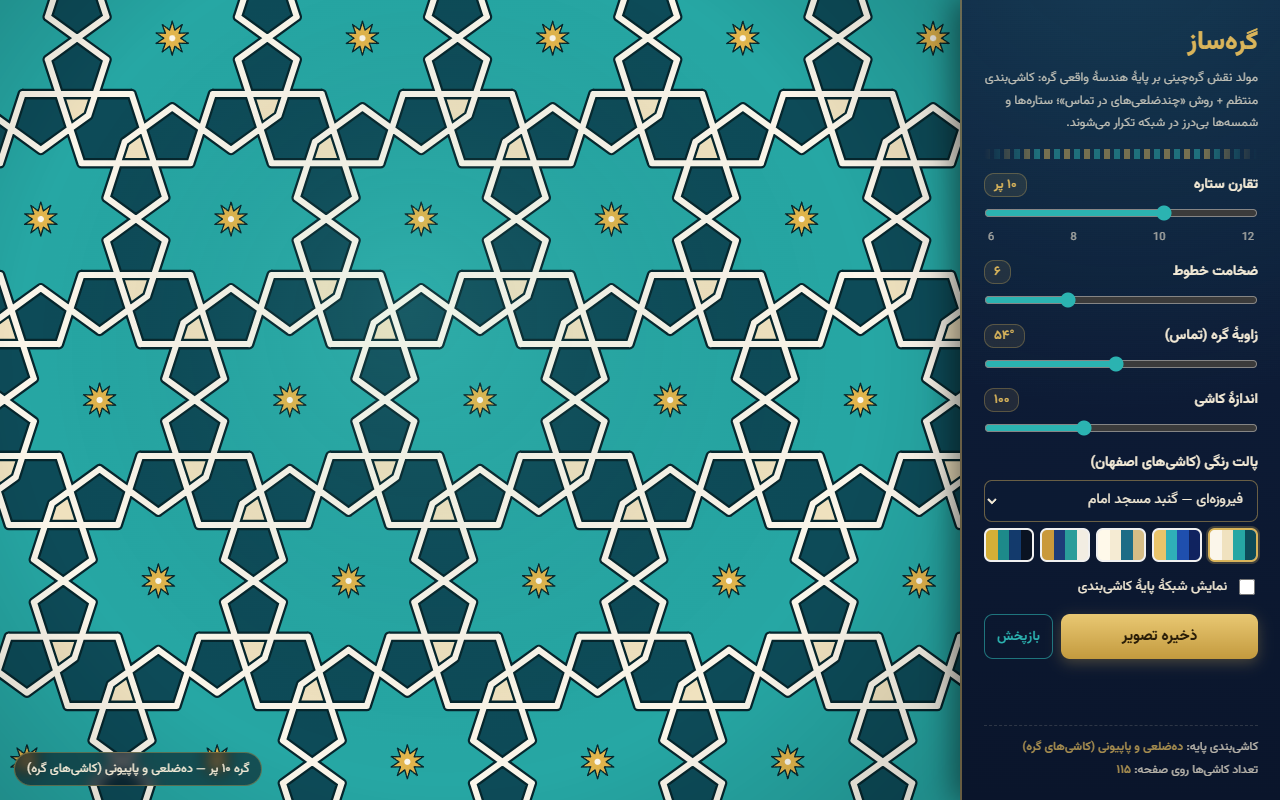 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
BazaarchehS8
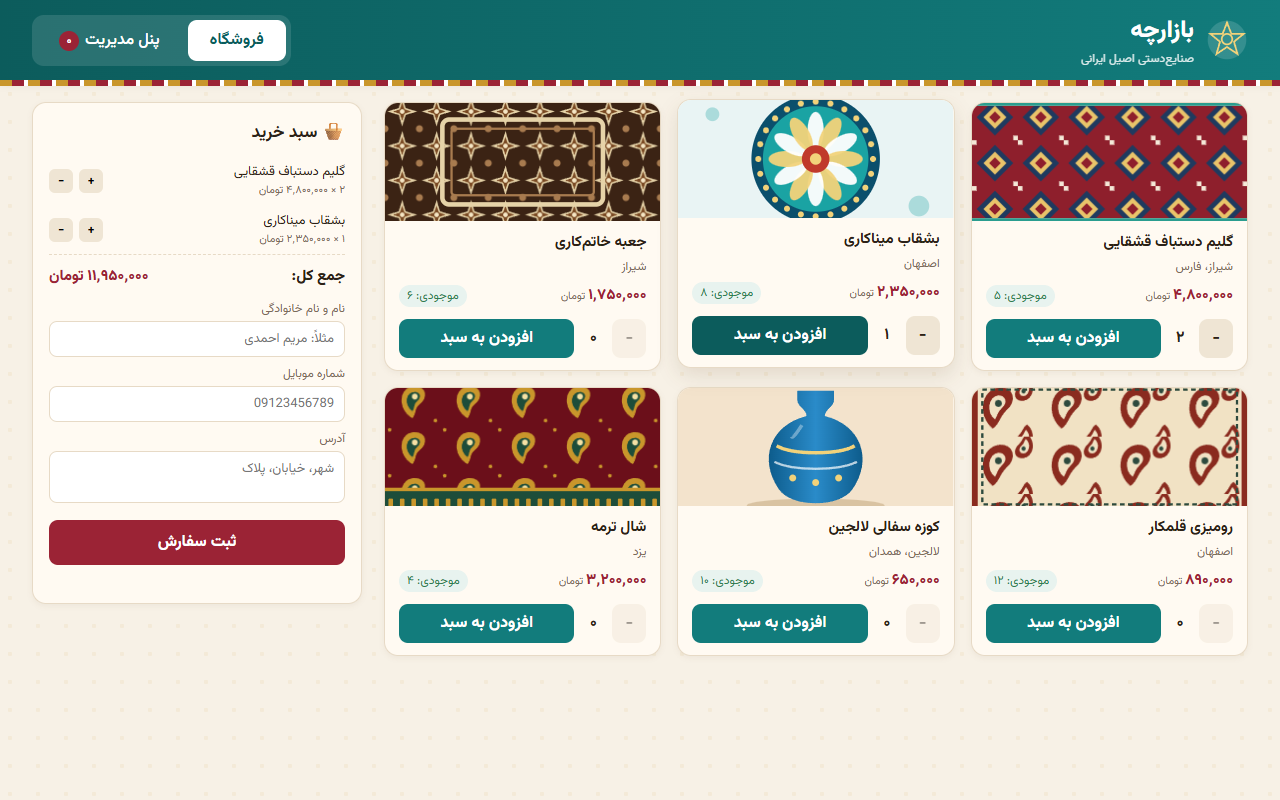 Anthropic: Claude Opus 5.5 · 7.5 of 7.5
04Quality versus cost
Each dot is a model. Higher and further left (cheaper) is better value. Cost is what the model itself charged to answer the whole test, without the jury. The cost axis is logarithmic.
YouTube · @MrMpAI
Every new model, a new episode
I review each model’s results on camera on my YouTube channel: I run its builds, compare them with the champion and give my own verdict. The videos are in Persian.